Research · AI Security
Securing AI Systems: Prompt Injection and Data Poisoning
AI systems can be attacked through their inputs, their training data and the tools they can reach. Securing them means extending familiar security practice to new attack paths such as prompt injection and data poisoning.
The AI Attack Surface Stack
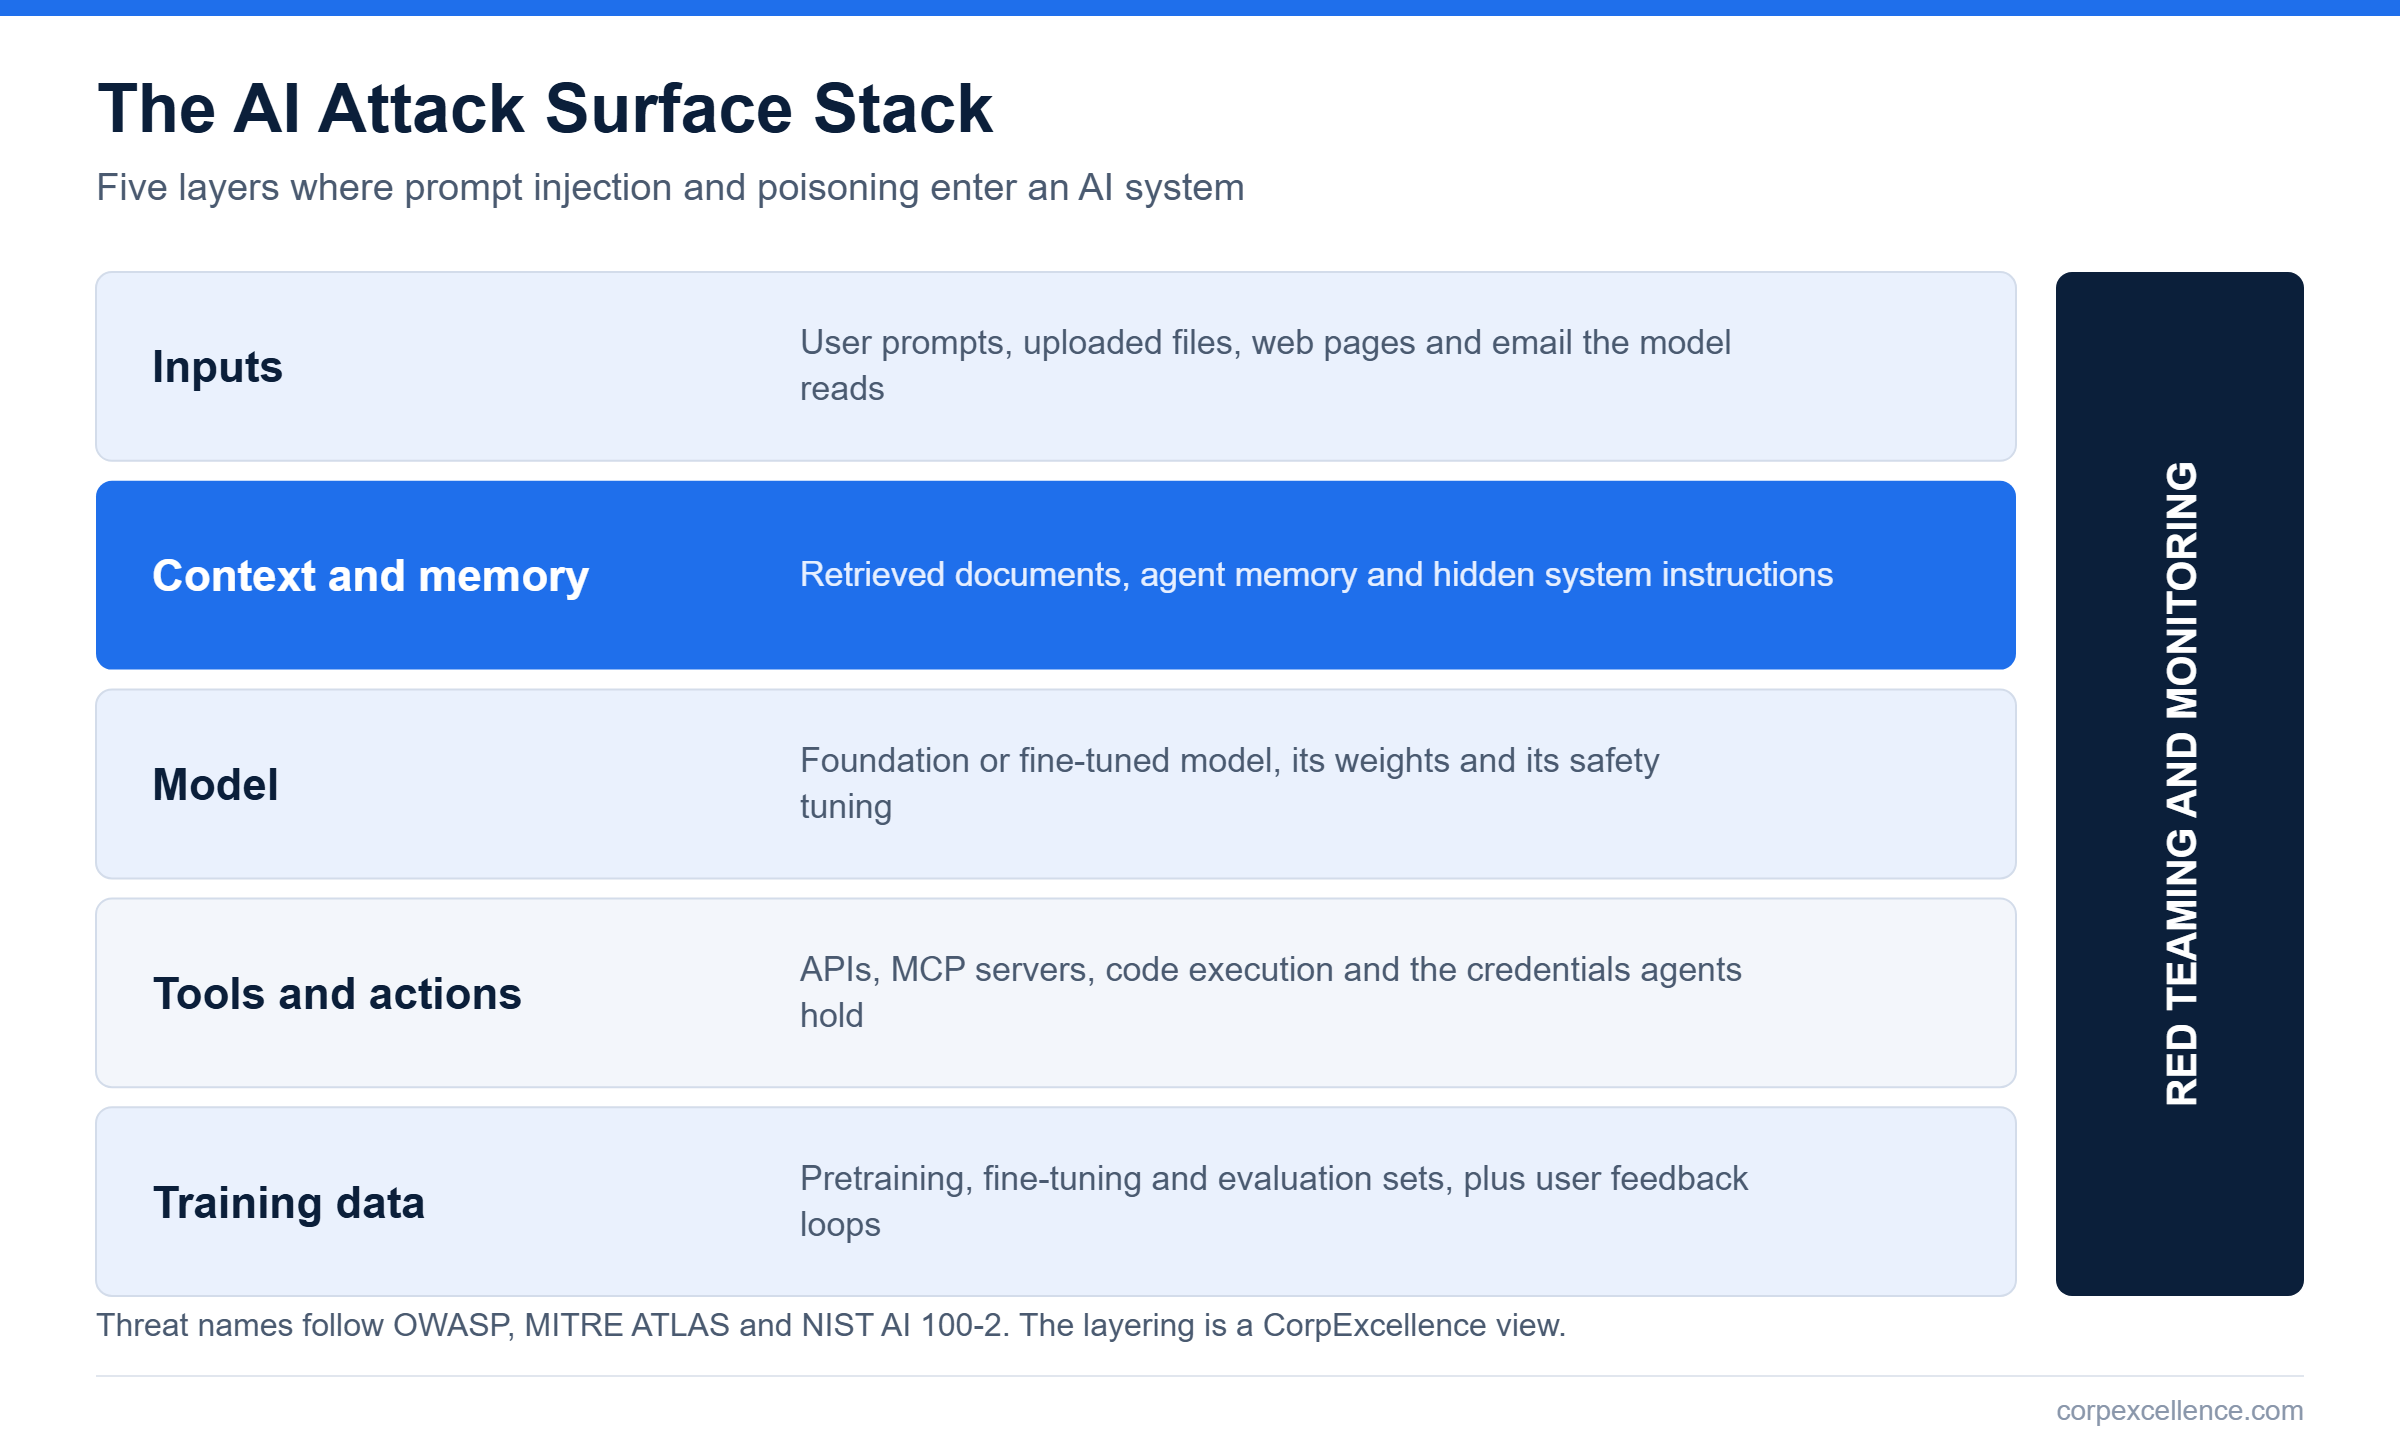
Prompt injection and data poisoning are not exotic model flaws. They are what happens when an AI system treats untrusted content as instructions or as fact. The AI Attack Surface Stack, a CorpExcellence framework, divides an AI application into five layers so each team can see where hostile content enters and which control owns it. The threat names come from public taxonomies such as the OWASP Top 10 for LLM Applications and MITRE ATLAS. Only the layering is ours.
Inputs and context: where injection starts
Direct prompt injection arrives in what a user types. Indirect injection matters more for enterprises: instructions hidden in a web page, a shared file, an email or a retrieved record that the model reads while doing its job. Retrieval indexes and agent memory make the attack persistent, because one poisoned entry can steer many later sessions. Treat everything in the context window as untrusted data, tag each item with its source, and keep secrets out of system instructions, since models can be coaxed into revealing them.
Model and training data: where poisoning lives
Data and model poisoning corrupt behavior before deployment. An attacker who can influence scraped pretraining data, fine-tuning sets or user feedback loops can plant a backdoor that stays dormant until a trigger appears. NIST AI 100-2 E2025 classifies poisoning as an attack on the training stage and sets out the shared vocabulary for these attacks. Controls include provenance checks on every dataset, evaluation sets the training pipeline cannot modify, and behavioral tests for known triggers before each release.
Tools and actions: where damage happens
An injected instruction does limited harm if the model can only produce text. It becomes an incident when the model can send email, move files or call an API. The OWASP Top 10 for LLM Applications 2026 moved Excessive Agency from sixth to third place, and the OWASP Top 10 for Agentic Applications puts agent goal hijack and tool misuse first and second. Practical controls:
- Give each agent its own identity with least-privilege, short-lived credentials.
- Require human approval for irreversible or high-value actions.
- Validate model output before it reaches a browser, shell or database.
- Log every tool call together with the context that triggered it.
Prompt injection cannot yet be prevented reliably
Governing Agentic AI 2026 shows how to design agents so a successful injection does limited harm: scoped identities, gateway-enforced tool access, provenance tagging, runtime budgets and tested kill switches.
Where the industry is now
As of September 2026, the OWASP 2026 edition keeps prompt injection at LLM01 and renames system prompt leakage as Hidden Context Exposure. MITRE ATLAS added more than 45 techniques and sub-techniques in its April 2026 update, with a focus on agentic systems, and has moved to monthly releases. Reliable prevention of prompt injection remains an open problem, so the working approach is containment: limit what a hijacked model can reach, and run red team exercises that target indirect injection paths.
Common pitfalls
- Relying on a system prompt that says “ignore malicious instructions” as the main defense.
- Connecting agents to tools with a shared service account that has broad rights.
Research report
Secure AI agents by limiting what they can do
The 67-page report maps the OWASP Top 10 for Agentic Applications to six control planes and includes a tool and MCP server intake review and an agent incident response runbook.
Featured research report
Governing Agentic AI 2026
67-page playbook for governing enterprise AI agents: autonomy levels, risk tiers, agent identity, MCP controls and human oversight. Includes 10 ready-to-use templates.
Questions leaders should ask
- Have our AI applications been tested for prompt injection?
- What is the worst action an attacker could make our AI agent take?
- Can our AI applications leak data from other users or systems?
- Do we log enough to investigate an AI security incident?
More in AI Security
Related research reports
In-depth reports with ready-to-use templates.
- Governing Agentic AI 2026$59.99 PDF report
Latest Analysis: Securing AI Systems
Explore focused research and implementation guidance on this subtopic. The latest articles appear here automatically.
Related research reports
Reports connected to this topic.