Research · AI Infrastructure & Operations
Model Evaluation & Monitoring
Evaluation tests whether an AI system is good enough before release. Monitoring checks that it stays good enough in production. Both are essential, and generative AI makes both harder than for traditional software.
The Eval-Driven Quality Loop
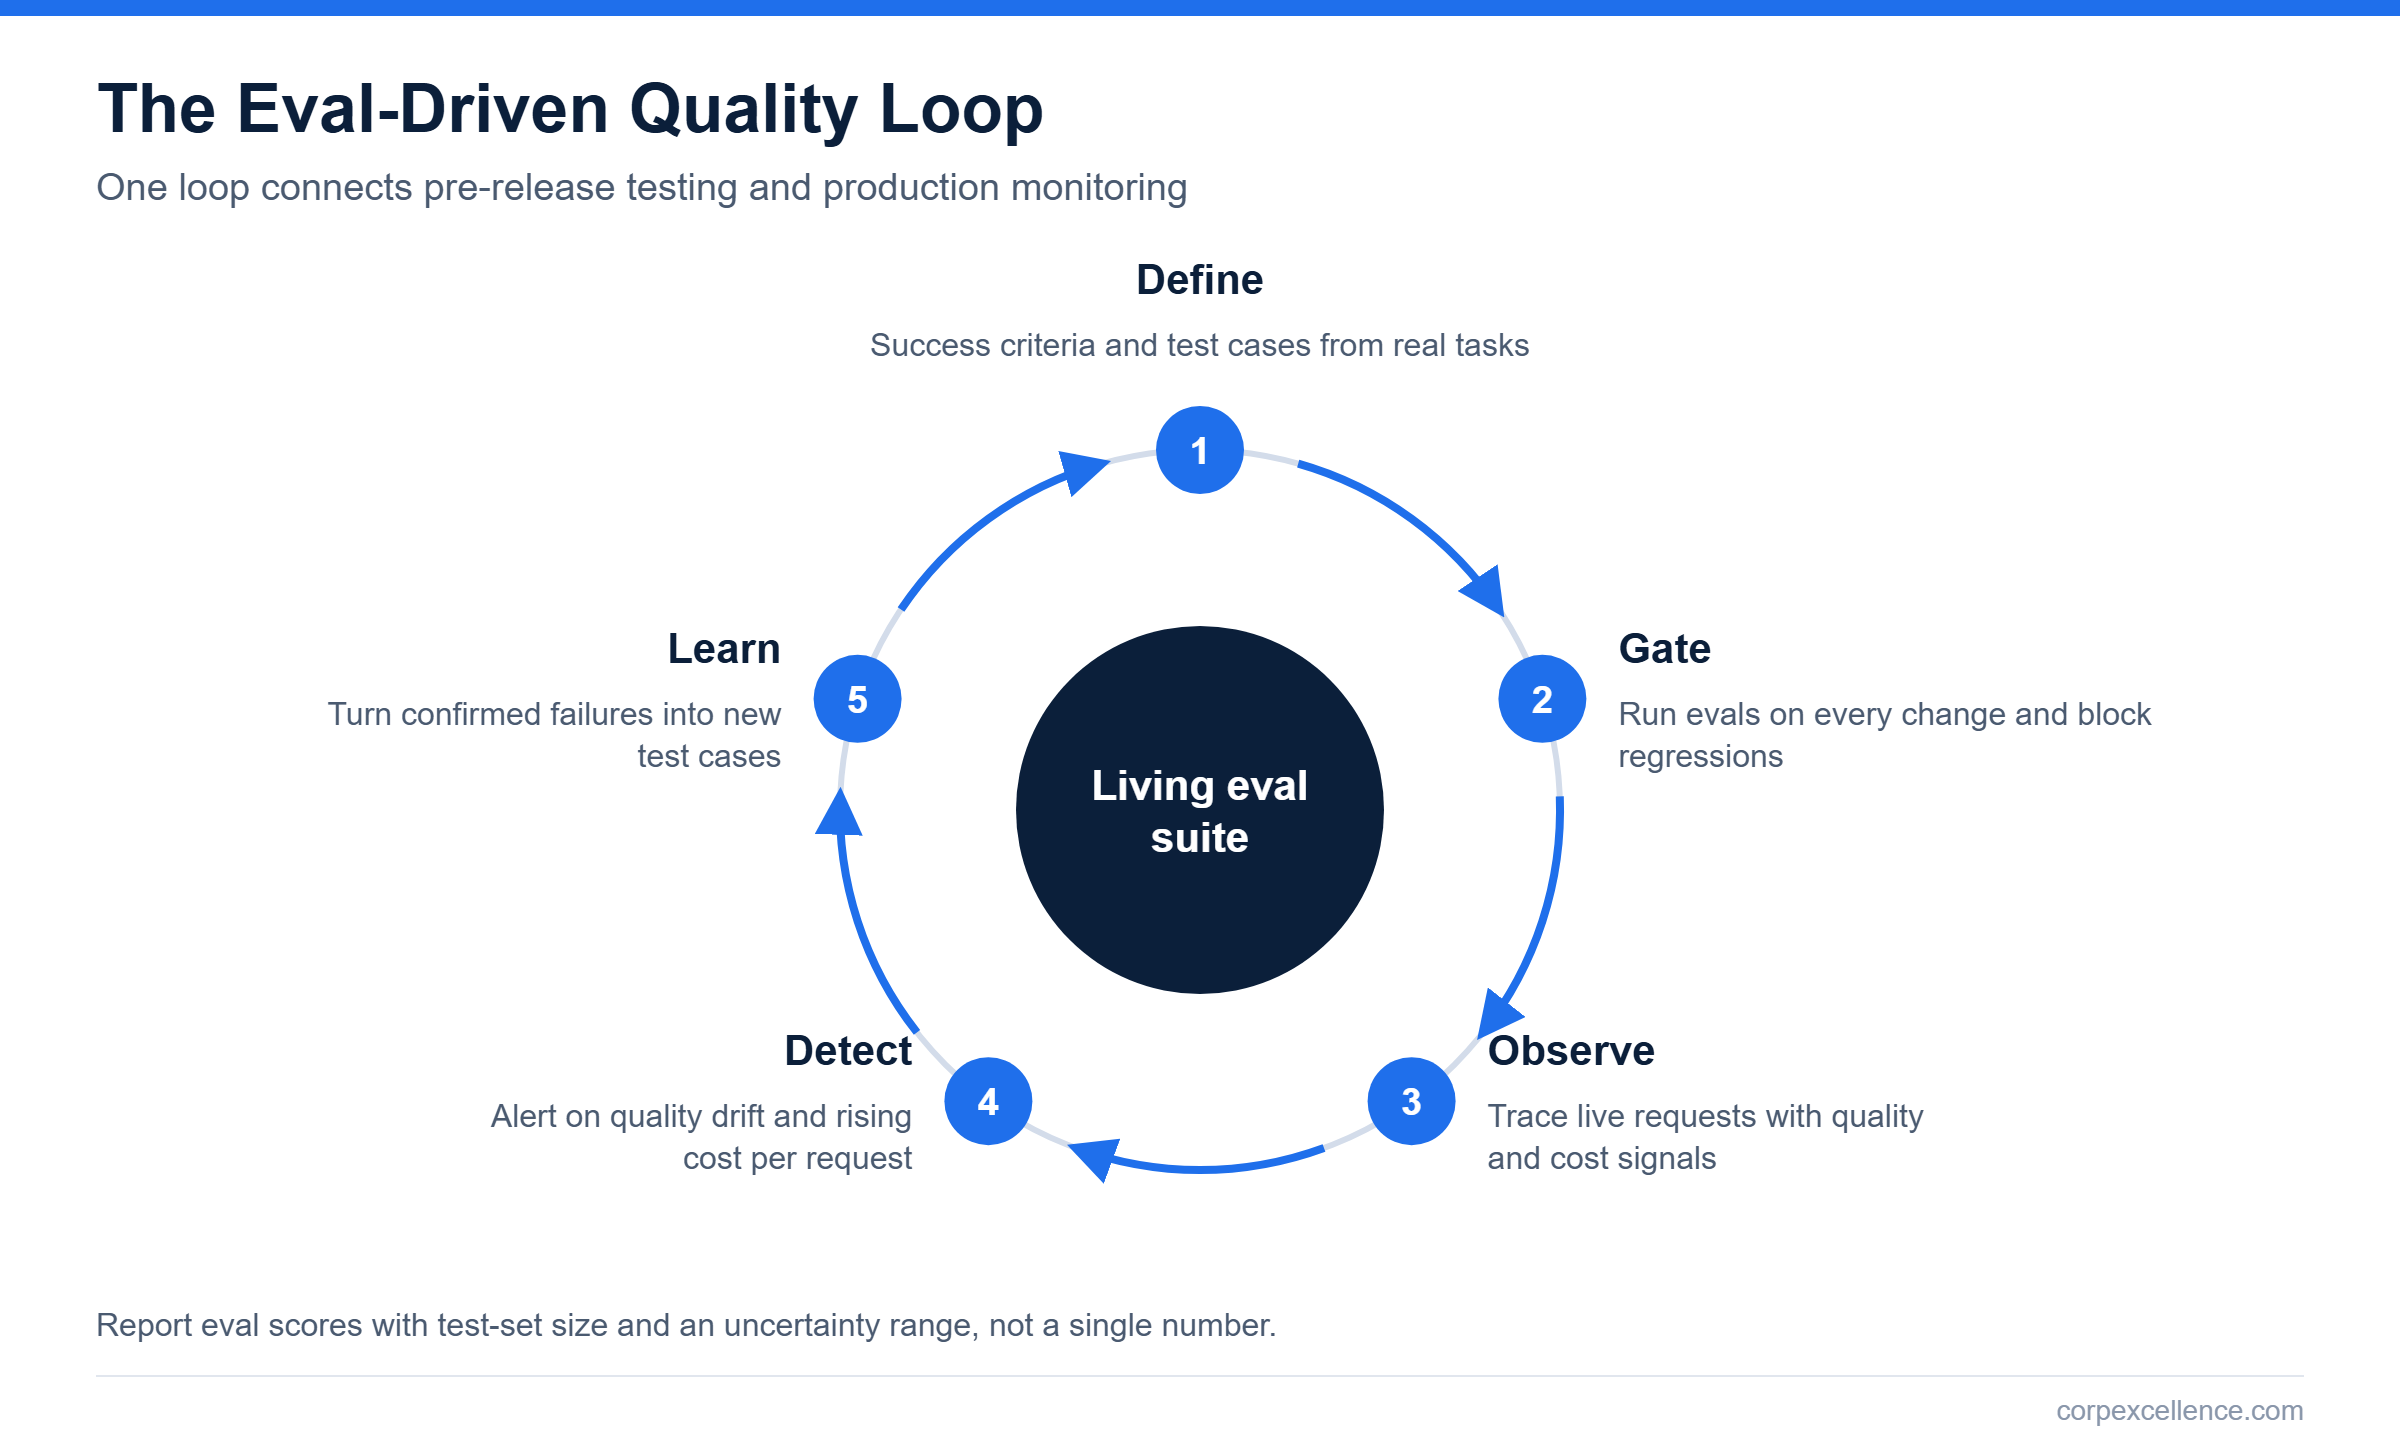
Evaluation and monitoring work best as one loop, not two separate projects. The CorpExcellence Eval-Driven Quality Loop treats the evaluation suite as a living asset. It is written before the system is built and grows every time production reveals a new failure. Teams that work this way learn whether a new model or prompt is better before their users do.
Define
Start with the task, not a public benchmark. Write down what a good answer looks like for your use case and build a test set from real inputs, including hard and adversarial cases, plus cases where the right answer is to refuse or escalate. Agree on pass thresholds with the business owner. Public leaderboards measure general capability and rarely predict performance on your own documents and workflows.
Gate
Run the suite automatically whenever the model, prompt, retrieval settings or agent tools change. Combine automated checks with human review for the cases that matter most. If a model acts as the grader, compare its scores with human labels on a sample before you rely on it. Track results over time so you can see slow erosion, not just sudden breaks.
Observe
In production, capture a trace of each request, including inputs, retrieved context, tool calls, outputs, latency and token cost. Add lightweight quality signals such as user feedback and sampled grading of live answers. Apply the same privacy rules to traces as to the data they contain, since prompts often hold personal information.
Detect
Alert on movement, not only on outright failure. Watch for falling sample scores, shifts in what users ask, more safety flags and cost per request creeping up. Silent provider model updates are a frequent cause, so record which model version produced each answer.
Learn
Every confirmed failure becomes a new test case. Over time the suite reflects how the system is really used, and the gate gets stricter exactly where it needs to. Review a sample of passing outputs too, since a test suite only catches the failures someone thought to write down.
Where the industry is now
Evaluation is maturing into a measurement discipline. NIST’s Center for AI Standards and Innovation issued NIST AI 800-2, a draft on practices for automated benchmark evaluations of language models and agents, in January 2026. In February 2026 it published NIST AI 800-3, which shows how to quantify uncertainty in benchmark results. The lesson for enterprises is simple: report eval scores with test-set size and a confidence range, and treat small differences between models with caution. For monitoring, OpenTelemetry’s GenAI conventions offer a shared trace format for model and agent calls, though they are still in Development status as of September 2026.
Common pitfalls
- Choosing models from leaderboard rankings alone.
- Evaluating once at launch and never again.
- Trusting an AI grader that was never checked against people.
- Monitoring latency and errors while ignoring answer quality.
Questions leaders should ask
- What evaluation must each AI system pass before release?
- How would we notice if answer quality declined?
- Are our automated graders checked against human judgment?
- When did we last re-evaluate each production AI system?
More in AI Infrastructure & Operations
Related research reports
In-depth reports with ready-to-use templates.
- AI-Ready Data$59.99 PDF report
Latest Analysis: Model Evaluation & Monitoring
Explore articles addressing this research topic as new analysis is published. The newest articles appear here automatically.
Related research reports
Reports connected to this topic.